 PH
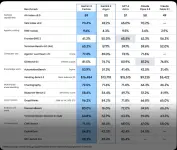
1/8 — Google just raised the bar with Gemini 4 Carbon.
Google's latest AI model is putting up some impressive numbers against GPT-6 Astra and Claude Opus 5.5.
It leads 15 out of 17 benchmarks in Google's comparison.
Let's break it down.
2/8 — General Intelligence
Gemini 4 Carbon takes the lead on AA Index v5.0:
- Gemini 4 Carbon — 59
- Claude Opus 5.5 — 58
- GPT-6 Astra — 57
- Gemini 4 Argon — 50
3/8 — Agentic Coding
Carbon is showing serious improvements in coding benchmarks.
- SWE-sweep: 9.6%
- Terminal-Bench 4.0: 65.2%
- FrontierSWE 2: 61.2%
The coding race is far from over.
4/8 — Computer Use & Automation
This is where things get interesting.
Gemini 4 Carbon scores:
- Agents' Last Exam: 77.4%
- OSWorld-2.1: 81.5%
- AutomationBench: 53.9%
Different models, different strengths.
5/8 — Long Context
Look at GraphWalks (256K–1M tokens):
- Gemini 4 Carbon — 96.2%
- Gemini 4 Argon — 84.2%
- GPT-6 Astra — 71.8%
- Claude Opus 5.5 — 66.8%
6/8 — Science & Cybersecurity
Carbon also posts strong results in technical evaluations.
- RiemannBench: 80.0%
- Terminal-Bench-Science: 64.8%
- CWE-bench: 71.0%
- ExploitGym: 54.8%
- SEC-bench Pro: 88.2%
7/8 — Gemini vs GPT vs Claude
So who's winning?
Gemini 4 Carbon leads most benchmarks in Google's comparison.
GPT-6 Astra leads FrontierSWE 2.
Claude Opus 5.5 leads OSWorld-2.1.
Carbon looks extremely competitive, but benchmarks aren't the same as real-world performance.
8/8 — The Takeaway
Gemini 4 Carbon shows substantial improvements over Argon, particularly in long-context reasoning, automation, and technical tasks.
However, pricing, reliability, speed, and real-world developer experience will determine how useful it becomes.
Is Gemini 4 Carbon the new AI model to beat?
What's your pick: Gemini, GPT, or Claude?