 PH
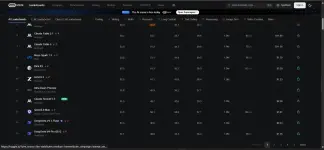
Sonnet 5.5 enters the board at #12 overall with an aggregate score of 51.5:
It sits directly below Shanghai AI Lab’s Atria Dawn Preview (51.6) and edges out Qwen3.8 Max (51.5) and DeepSeek-V4.1-Flash (51.3).
Notably, Anthropic’s flagship tiers—Claude Fable 5.1 (#6) and Claude Fable 5 (#7)—still lead their internal roster with 54.3 and 53.9 overall, but Sonnet 5.5 brings a solid balanced baseline across tasks.
 Pricing & Efficiency
At $2.38, Sonnet 5.5 is positioned as a high-efficiency mid-tier workhorse. Compared to the heavyweight Fable models sitting at $11.90, it delivers most of the punch at ~80% less cost—with a massive 1.0M context window standard.
Anthropic looks to be tuning Sonnet 5.5 for high-volume agentic workflows and long-document reasoning where the full Fable tier might be overkill.
- Coding: 49.7
- Writing: 42.6
- Math / Hard Reasoning: 39.3
- Context Window: 1.0M tokens
It sits directly below Shanghai AI Lab’s Atria Dawn Preview (51.6) and edges out Qwen3.8 Max (51.5) and DeepSeek-V4.1-Flash (51.3).
Notably, Anthropic’s flagship tiers—Claude Fable 5.1 (#6) and Claude Fable 5 (#7)—still lead their internal roster with 54.3 and 53.9 overall, but Sonnet 5.5 brings a solid balanced baseline across tasks.
Pricing & EfficiencyAt $2.38, Sonnet 5.5 is positioned as a high-efficiency mid-tier workhorse. Compared to the heavyweight Fable models sitting at $11.90, it delivers most of the punch at ~80% less cost—with a massive 1.0M context window standard.
Anthropic looks to be tuning Sonnet 5.5 for high-volume agentic workflows and long-document reasoning where the full Fable tier might be overkill.